Your baseline
μᵤ = mean(your real diary ratings)
Start with how you use the star scale, not somebody else's 3.5.
Prediction methodology
Kinolog does not ask a language model to guess a number. The personal star is produced by a structured model over your own ratings, film metadata, similar movies, and the record of where earlier estimates were wrong.
The prediction is still an estimate. A thin diary, a movie unlike anything you have rated, or taste that changes with context can all make it miss.
Tonight
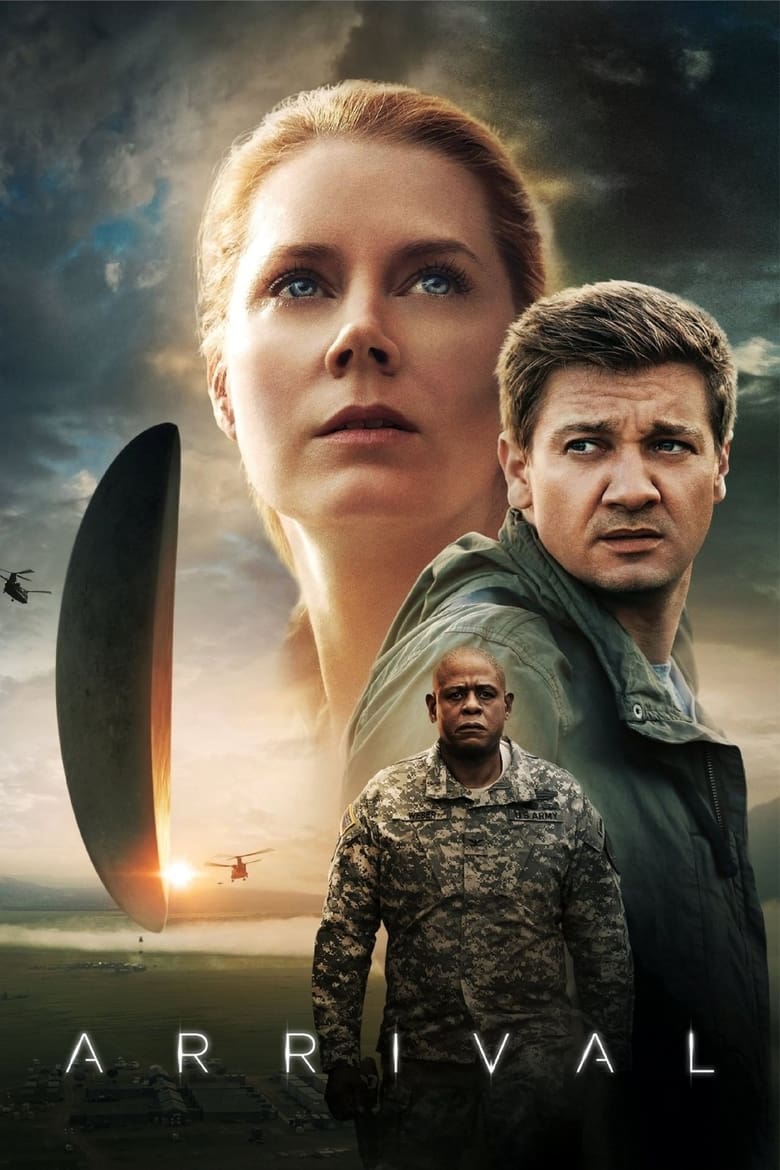
Arrival
2016 · 116 min · Science fiction
4.4★predicted for you
Why 4.4★
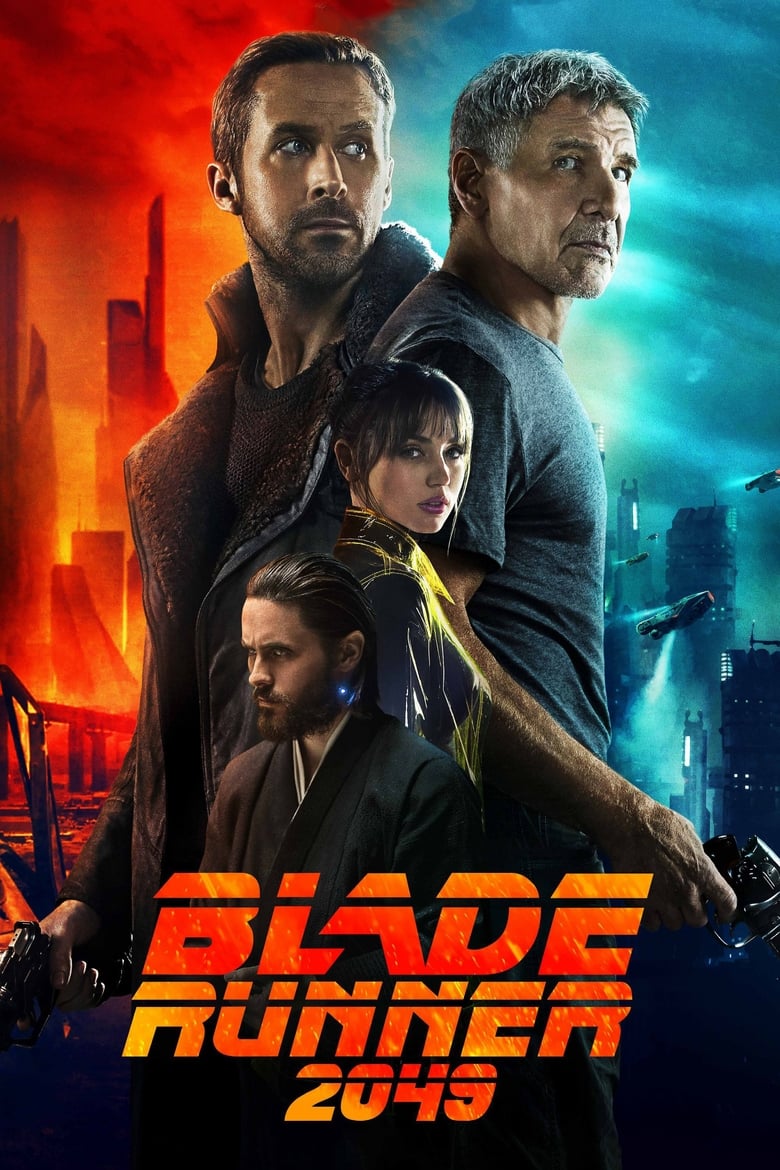

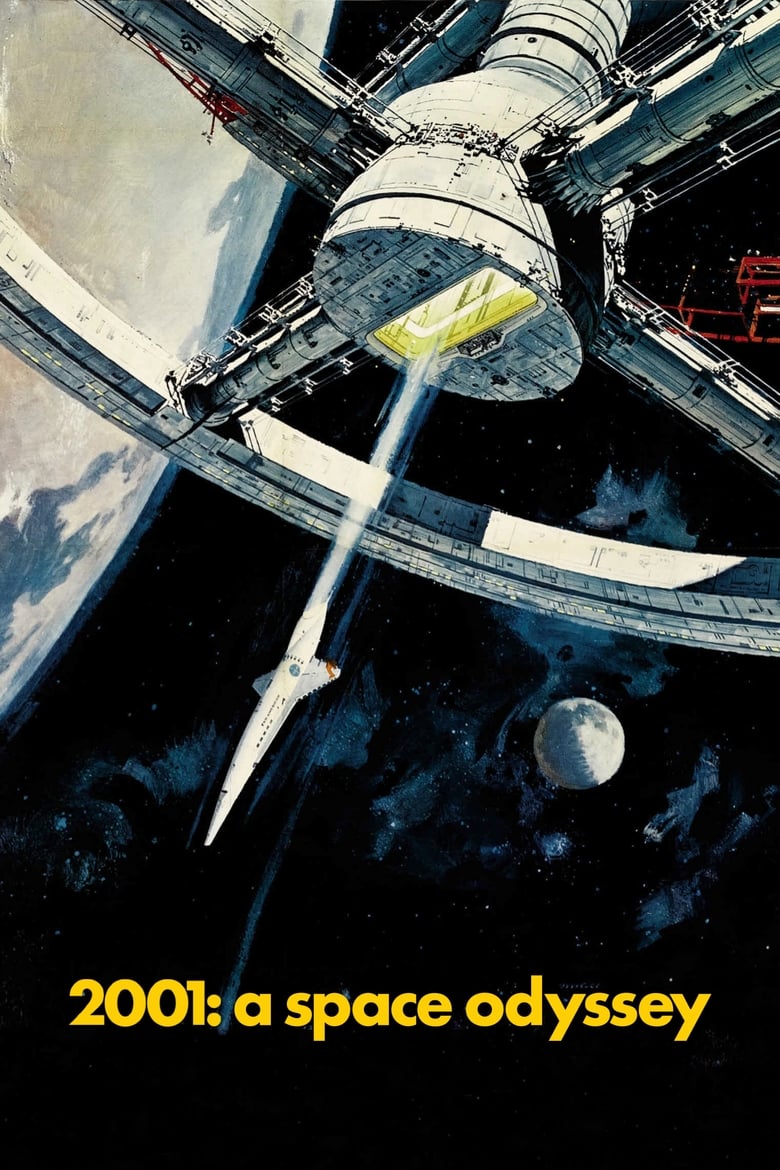
You rated these 4.5★ and up: quiet, idea-driven science fiction.
The short version
predicted stars = personal baseline + similar-film shift + taste-feature shift
+ personal crowd prior + learned correction
The result is rounded back onto Kinolog’s star scale and kept between 0.5★ and 5★. No single genre, director, crowd score, or past miss is allowed to move the number without a bound or an evidence check.
The arithmetic
μᵤ = mean(your real diary ratings)
Start with how you use the star scale, not somebody else's 3.5.
dƒ = mean(rating − μᵤ)
Directors, genres, eras and other traits are measured as departures from your own baseline.
trust = (n − 1) / ((n − 1) + λ)
A single film gets exactly zero influence. Repeated evidence can pull harder; thin evidence shrinks toward zero.
bias = clamp(mean(actual − predicted) × n / (n + 8), ±0.4★)
After at least six later ratings, a persistent high-or-low miss can gently correct future estimates.
1 · Your scale first
Some people live between 3.5 and 5. Others use the whole scale. Kinolog centers its effects around your own average rating, so the model asks whether a film should land above or below your normal level before it turns that shift back into stars.
Calibration answers can help the model understand what moves you, but once a real diary exists they do not quietly become watches or rewrite the baseline of your actual history.
Illustrative evidence
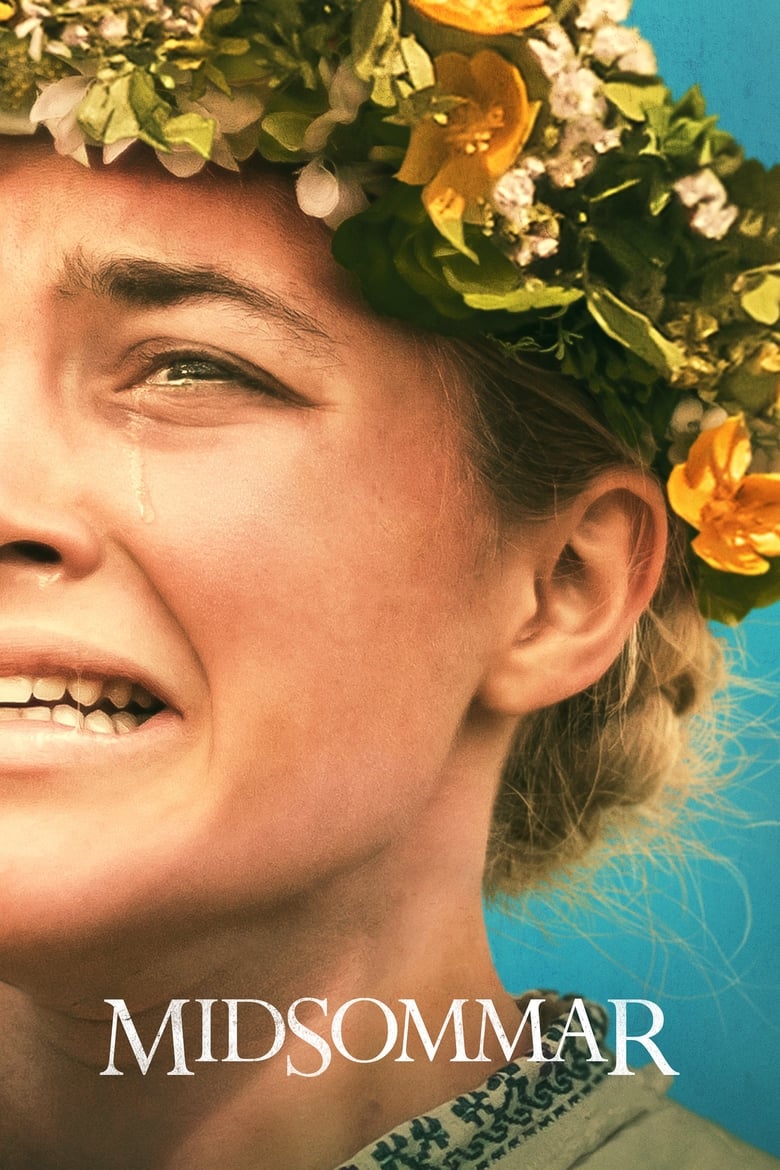
Midsommar
Hereditary
The Witch
2001: A Space Odyssey
Calibration can provide an early read. Real diary ratings eventually become the stronger anchor because they carry an actual watch, your exact star and, when known, when it happened.
2 · The forces
The candidate is compared with films you rated as complete objects: genres, subgenres, people, era, runtime and audience reception. The closest matches dominate; weak lookalikes do not win by being numerous.
If you repeatedly rate a director, subgenre, genre or era above your own baseline, that can move the call. Every effect is shrunk toward zero when the sample is thin.
TMDB's 0 to 10 audience score is never added directly to your 0.5 to 5 stars. Kinolog fits a small ridge-regularized regression between your ratings and crowd scores. If you often disagree with the crowd, the slope stays shallow.
Later ratings can reveal that the model consistently runs high or low on you, or on a well-supported slice such as a genre-era combination. Corrections require a sample, shrink toward zero and are capped.
Normalization
Kinolog does not put raw values like “year 2017,” “runtime 142,” “TMDB 8.1,” and a genre flag into one unscaled linear formula. That would let feature magnitude become a modeling decision by accident.
Instead, the rating target is centered on your own scale. Taste features become deviations measured in stars. Similarity is bounded. The crowd score is centered inside its own personal regression. Sparse evidence is shrunk before it contributes. Those transformed terms are what are combined.
So “normalization” here is mostly architectural: put each active signal into a comparable, bounded meaning before it can move the final star. It is not a blanket z-score applied to movie labels.
How we test it
For a held-out watch, the evaluator trains only on ratings that existed before it. Future films cannot leak into the model that supposedly predicted the past.
The harness tracks mean absolute error, root mean squared error, coverage and error by confidence. A model that predicts almost nothing does not get to look good just because the few surviving calls were easy.
The base architecture was tuned with diary-level holdouts, so one person's ratings were not used to choose the parameters that later scored that same diary. The newer closed-loop corrections are evaluated separately and are not presented here as accuracy-proven.
The product only calls a number an issued prediction when the exact star was disclosed before the later watch. Hidden Free estimates may help internal learning, but they never become a retroactive 'Kinolog said…' receipt.
Confidence
Kinolog’s hunch / read / confident labels describe the strength and agreement of the evidence behind a star estimate. They are not calibrated probabilities of enjoyment. Observed reliability can lower a confidence label when a sufficiently large slice has performed poorly; a lucky small sample is never allowed to promote one.
Limits
A movie unlike your history, a tiny diary, a rating scale that has changed over years, context the metadata cannot see, or simply a surprising reaction can all defeat the estimate. The explanation is evidence to inspect, not proof that you will like the film. Kinolog does not publish a site-wide accuracy percentage as a promise about your own future ratings.
The final test is yours
When a disclosed call settles against your later rating, Kinolog keeps the result. Your own record is more useful than a site-wide accuracy number that says nothing about how this model performs on your taste.